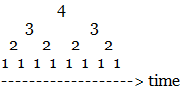Friday, March 23, 2012

Intervals vs integers and why computers can't count

Counting
It struck me the other day that computers don't count that well and that there is a probably better form of binary.
Above shows the points where each bit flips as we count upwards from zero, giving our well known 0000 0001 0010 0011 0100 etc.
For an arbitrary length number this isn't a great system because many bits have to be flipped on the same clock tick. In fact the number of bit flips is unbounded, so to simply add 1 to 65535 for example we have to flip 16 bits. The worst case comes when going from -1 to 0, where every single bit must be flipped, an infinite task on an unbounded integer.

Instead computers could use a symmetrical system that flips the bits like so:

There are fewer bit flips and to count upwards you only need to flip one bit each time, giving 0000 0001 0011 0010 0110 0111 0101 0100 1100 etc.

Intervals
Counting is a transition each tick, which takes you from one state to another. Therefore the states represent the period between the transitions, they are a set of intervals, just like a year or an age is an interval. If I say I am 25 then I am talking about a year-long interval. The set of intervals are different than the set of integers, unlike integers, intervals don't have a multiply since the result wouldn't be in the set of unit long intervals.
Given that our binary strings represent intervals, we can see how much cleaner it is to represent them this new way:
or as bit strings:
As you can see, the bit string is symmetrical around 0, so the top bit is effectively just a sign bit.

With the existing form of binary there is a choice of how to represent negative numbers, you can either have a sign bit, or you can use the result of extending the subtraction algorithm beyond zero (called the two's complement method). Whereas with this new binary system you don't have to choose as they are one and the same, negatives are a natural extension.

Integers
As I said, counting is switching between values each tick, so the values naturally represent the interval. If you want to store an integer rather than an interval then that is a trickier problem, currently computers simply consider the integer as the floor of the interval value, and we can do so in this case as well. The + and - will work as it did on the intervals, you just need to be careful in implementing the multiply function.
If we weren't worried about memory it is cleaner to make a new symbol 'c' meaning 'changing between 0 and 1', then you can see the integers are also symmetric:

Summary
Counting naturally operates on the set of intervals ..-2,-1,-0,0,1,2,..
'Symmetric binary' more naturally represents these intervals, and is faster for counting.
The integers (..-2,-1,0,1,2,..) are usually represented as the floor of the interval value, so are a derived representation.

The integer above any interval 1000... occurs at 2^n

Beyond binary
This symmetric system works best in binary since each digit changes at a regular pace, perhaps this is why we haven't used a symmetric system for decimal, and perhaps why we didn't consider this symmetric system when moving from our decimal into a binary form for computers. But we can do a decimal version, in it we can write the years up to and after the year 2000 change over:
1003 1002 1001 1000 2000 2001 2002 2003 2005 2005 2006 2007 2008 2009 2019 2018...

I could also imagine a long lost tribe somewhere using this system base 6 as you can count it on your fingers:
0 1 2 3 4 5 15 14 13 12 11 10 20 21 22 23 24 25 35 34 33 ..

[Update: reading more about non-standard number representations, it looks like the binary numbers are called Gray code (or reflected binary) and the general system is called n-ary Gray code. There is nothing new under the sun or so they say... even to Gray, as Stibitz described it earlier.]

Wednesday, March 14, 2012

Implementing fractal automata

Assuming you have a knowledge of how Conway's life or other cellular automata are implemented, here is a summary for making fractal automata.

Data structure
Your data structure needs to be a set of grids like so, doubling in their resolution each layer.
so the resolution of layer n is 1 << n by 1 << n. Each square just holds a boolean value. 1 or 0.

The new value at each square is a function f of its neighbours values (including its own present value), for example here are the neighbours of the red square:
You might say that the orange squares are its siblings, the yellows are its children and parent. I also sometimes include the grey squares as neighbours of the red square.

Each square is then updated independently according to function f. Like other cellular automata, you need to have a separate copy of the grid hierarchy so you can 'double buffer' and the change in one cell doesn't affect the others on that frame.

Layer order
The layers must be updated in a specific order, which appears like so:
So on frame 1 you update layer 3 based on its siblings and its parent(s). Since there is no layer below you can treat the layer below as being zeros, just as we do for the neighbours outside of the edges of the grid. On the next frame, update layer 2, then the next frame update layer 3 and so on.

Despite appearances the order is quite easy to calculate. Take the frame number in binary and find the position of the first 1 in it-
In our example we have four layers, so our depth is 4. If p is the position of the first 1, then:
layerToUpdate = depth - 1 - p.
To prevent overflow, add:
if layerToUpdate < 0
{
frame = 1;
layerToUpdate = depth-1;
}

The function f
The function f is the set of rules determining whether the centre square 'lives or dies', or you can call it the mapping from the neighbour values to 0,1. The number of mappings is so large that it helps to try out different simpler rule sets. For example a mapping based on the number of 'on' neighbours without worrying about where they are placed.

Friday, February 10, 2012

Extending convolution

I propose a new operator which is like convolution so I'll call it covolution for the sake of this discussion:
C = B * M where * is the covolution operator.

The base data B is a set of detail levels of single-bit grid trees of some dimension n, so an example in one dimension:

Additionally you have the mask that applies the change to the base data. This is a mapping from each possible permutation of the local neighbourhood to a new bit value for the centre of the mask. For example for the red 1 in the above diagram, an example local neighbourhood is:

The red position takes into account the three nearby higher level bits, the two neighbouring bits on its level, plus itself, and the two lower level bits below it, then maps this to a new bit value for the red position. This same mapping is applied to every bit in the base data B, resulting in the new covolved data C.
In the example above, there are 8 bits in the neighbourhood, therefore 2^8 permutations to map to 0 or 1. i.e. it is a 256 to 2 mapping which can be stored as simply the set of patterns that result in a 1. Neighbourhoods of any size are allowed, since the operator 'covolves' two arbitrary datas of this structure.

For 2d base data, the higher levels can be thought of as coarser resolution images:
A neighbourhood in 2d may choose the 4 nearest parents, the 9 'Moore' neighbours and the 4 immediate children, requiring a mapping of 2^17 to 2.
You may have noticed that this is similar to Conway's life game, which is a convolution of such a 2d grid with a 3x3 neighbourhood mask. With covolution we can do Conway's life, but the extra detail levels mean that it is continuous spatially, rather than a grid:
This example uses a 3x3 parent neighbourhood only, and the mapping acts to smooth corners and remove some cells that are completely enclosed. It is a covolution applied multiple times to base data with initially only the highest level 4 pixels set to 1. Note that the patterns exist at all scales but don't repeat themselves in a simple way, due to the cellular automata nature of the operation.


Covolution can also apply to real values rather than bits, much as convolution usually is applied to real values. You replace the mapping with simply scaling each neighbour value by the mask value and summing, just as with convolution, much like is done with 'soften' and 'sharpen' filters in image packages.

Further, covolution can apply to any data structure rather than bits or reals, and the mapping can be chosen as any function that maps the neighbourhood to a new value of the data structure.

These are not actually different operations, they all are derivable from the bit version, which is ultimately the most general definition.

Continuous Time Covolution
The covolution operator acts instantaneously. It would be tempting to create an animated set by repeated covolutions: B = B*M, but this is not right, since the 1 dimension of time can't be built from multiple 0 dimensional covolutions. Instead we include scale symmetry to time also:
Just like with space, time is also broken into shorter sections for the higher detailed grid levels (like level 1). This leads to an order in which to individually apply the covolution for each level:
1,2,1,3,1,2,1,4,1,2,1,3,1,2,1,....

So a covolution applied in this order is called a covolving system. It is continuous in space and time, and means that the fine details change faster than the larger shapes on the coarser levels, producing true dynamic fractals as seen here:
Various covolving systems, simply by adjusting the mapping.
The only difficulty is finding interesting mappings. Since there are 2^17 neighbourhood patterns, there are 2^(2^17) possible mappings, which is a large search space.
The trick with finding interesting mappings is to use different constraints to search families of mappings. For example, a simple constraint is to map just the total number of neighbours onto the boolean output. Even with this simple constraint there are still 2^16 possible mappings, here is an interesting bacteria-like result:

Thursday, January 19, 2012

Thoughts on the universe's origin

One of the larger questions in physics or philosophy is where the universe came from. Lawrence Krauss's 'a universe from nothing' video got me thinking about it.
If we think of the universe as 4d space-time then it is just a geometry, unmoving, unchanging. We might ask why this geometry, but a starting question is, why is the time axis so different to the space axes?
Well, relativity tends to deal with how the two relate to each other, but why is there this strong dependency in the time direction?
An answer may be that the universe geometry in 4d is radial around a point, in 2d it might look like so:
The radial lines represent information, since there is a strong correlation along the length of the line, you might say that the direction of the lines (which for a small neighbourhood are roughly parallel) represents the time direction, and the other 3 directions are space directions.
Since the correlation is in this direction, it remains to decide which direction is forwards in time, this is simply the direction to higher entropy.
So I am suggesting that the time dimension is simply the one that happens to be the direction of the lines in this radial 4d shape. It explains why the universe appears to be expanding, is consistent with everywhere being equidistant from the 'big bang', and deals with why there is nothing before the big bang (because that is the centre of the volume), it is approximately the same reason that there is nothing north of the north pole, just a geometry issue with our way of parametising time.
Accelerations or decelerations of the expansion could be explained as changes in the density or roughness of these lines, effectively changing how much time is perceived to pass per unit distance along the line.

OK, so if we accept such an explanation of why we perceive a 3d universe changing through time, then the next question is: why is the universe geometry shaped like that and not some other shape?
We can't ask why there is matter in the universe, because matter is just energy (movement) which is just a correlation of information in the time and space direction. All that exists in this universe is just correlated information.
We can't ask what created this correlated information as we have removed the idea of time and cause and effect, so all we can really ask is: why is the information correlated as it is?
Which can be rephrased as: why are there these constraints on this information?

I can only consider this question speculatively... I am fairly certain that the only sensible answer is that there are ultimately no constraints on the information. In other words, each apparent constraint is an emergent constraint from the action of multiple, smaller level, less constrained information.
This idea can be seen right through physics, from Feynman's path-integral descriptions of particles, to entropic forces which explain elastic forces and probably gravity.

So at the highest resolution there are no constraints and therefore there is nothing that needs further explanation.
i.e. we are living by the high level laws that derive from infinite information acting without rules. Even logic and consistency needn't apply at the lowest levels, it is just that logic and consistency is more persistent, an invariant state or attractor of the mass of possible illogic.

Tuesday, October 18, 2011

3d numbers

This is the beginnings of an idea about 3d numbers. We have the complex numbers, which are complete, and beyond this we have quaternions and some other constructs, but no 3d numbers. As I'll show, developing a 3d algebra requires moving to multi-valued quantities.

So we have a 3d number a + bi + cj. Addition and subtraction are just element-wise. What about times and divide?
Well, a times b at its core means apply b to a as b is to identity (which is 1 in the reals). Note that this definition works for reals, complex numbers, integers etc.
So like in this diagram, let's say that a is 1+i and b is 1+0.1j. We take the identity to be 1, so b compared to 1 is a relative offset of one vector to another, defined by an angle and a scale, in this case an angle of about 0.1 radians and a scale of about 1.05 or something like that. So that describes how 'b is to identity'.
If we apply this relation onto vector a we have a problem, in what direction do we rotate away from a by this 0.1 radians? We have multiple answers, in fact b could sit anywhere in a circle around a, i.e. b maps out a cone around a, each b having a different phase phi.
At this point we could either say 'well that's no good, a*b must give a single answer' and leave it there. Or, as in this blog, we continue to build the algebra with these multiple results as a feature of the algebra, not as a problem.

So we have a multi-valued algebra where a*b is either a single value when b is a real number, or otherwise is the set of points on the circle of a cone.
So if c = a*b, and c is the circle, then what is c*d? Well for the same reasons it is a thick circle of a cone around a:
This starts to demonstrate that every multiplication makes the result less and less certain.
So, generalising, we can say that a*b is a sort of convolution of b onto a. And, we see that every 3d number is generically described by a probability density function over the whole 3d space.
Also notice that b*a is not the same result, so multiplication is not commutative in this algebra.

In this system we find that addition and subtraction are a convolution of the many-valued quantities, since we're adding all combinations that a and b can be.

Finally, what about divide? Well clearly you can divide in some cases, since it is just the opposite of the multiply. Statistically, we could generate the divide operator as c/b = a for all a and b where c=a*b. However, more work is needed to build a divide algorithm, and it doesn't seem that all numbers can be divided, but that isn't a hard requirement anyway.


So we appear to have a basic many-valued algebra. You can make a similar algebra on the real or complex numbers by allowing dual valued square roots for example, but this 3d algebra has uncertainty at its core. Is there anything more to it than described so far?

Actually yes, the algebra is more complex than it seems. We seem to have some contradictions,
Problem 1: a+a is not the same as a*2 since + is a convolution.
This is where the algebra gets more complicated. You see + is only a convolution if a and b are independent variables, if they aren't then + can act differently.
The way to calculate is to take the phase phi of all the independent variables in the equation as degrees of freedom, then allow each degree of freedom to vary when calculating the result. What we end up with in the general case is a path-integral formula, very similar to the maths of quantum mechanics.
As a result, we get values which are coherent or in phase, e.g. a and b where b=a, values which are out of phase, e.g. a and b where b=-a, and values that are independent, e.g. a and b.
So a*a is not the same as a*b where b is independently the same value as a.

we can draw a single possible phase for a single-value 3d number as a little flag on the end of the arrow, like this:
For a*b where b is independent but with the same value as a, then you get a circle like this, with all possible phases at every point on the circle:
For a*a we instead get the phases rotating with the circle:

Notice that the flags rotate twice around the full circle, since applying the twist phi twice in a*a.

So even though both these pictures are the same probability density function, they will be different if and when they are applied in other operations. For example, if you apply the independent variable d to these circles, you get a thick circle in the a*b case, and something like a thin cardoid in the a*a case.

In fact, we could continue to multiply a by a and get a growing double spiral probably. This roughly defines the power operator, and is much like a spreading wave.

Problem 2: a is not the same as 1*a, since 1*a generates a circle around the vector 1+0i+0j.
We need to distinguish between constants and variables here, we do this by prefixing constants with _. So _1*a = a, but 1*a is a superset of a, constants have phi = 0.

So, getting back to the data structure, a single 3d number is not only a probability density function but also a set of independent degrees of freedom, with a density function for each one. I think.


What is the use of such an algebra? Well it seems to have good links with quantum mechanics. It is interesting that the randomness is a sort of necessary result of extending into 3d.


Tuesday, January 11, 2011

Living on the hillside

I grew up on the side of a hill. There was always a view ahead of you wherever you were in the garden, and a steep bank behind you. Streams always ran downwards towards the view, ahead of me the future path of the water, and behind me the past.

When asked where the water in the stream came from I might have answered “from further up the stream”, and if questioned further I may have said “well from even further up”. From my knowledge of the garden where I played, and from my friends’ houses it would have been hard to comprehend how the streams could have a beginning and an end… and this isn’t surprising because almost all houses in hilly areas are on the side of the hill, very few indeed are right at the top or right at the bottom, very few places show where a stream actually starts.

As adults we sometimes think of time as flowing like a stream, it always comes from somewhere and goes to somewhere else. And here lies a puzzle for us… what was the first moment in time? And what came before that?

People answer in several ways, some say it’s impossible to have time before the big bang, others say there was just nothing before that, others suggest that there was a big crunch before the big bang, giving way to infinite repeated cycles of universes, so time goes on indefinitely. I would like to explain why I think it is probably none of these.

Just like growing up on a hillside, we are all on a different kind of hill, we are descending from order into chaos. I don’t mean this as dramatically as it sounds, this simply means that things are very very slowly becoming more disordered, it is called the 2nd law of thermodynamics and the chaos is measured as entropy and is slowly increasing.

Unlike what is often quoted of this law, there is not an inevitable march into chaos, but from the high perch of order that we are on in this universe each step in time is highly likely to increase disorder.

In this post I show how the total landscape of possible evolutions of the universe follows a fractal pattern which looks much like a hilly terrain through time, perched on the side of a hill looking downwards to a slowly more disordered future. When we look back towards what we think of is the beginning of the universe we are actually looking up to the top of this hill. As we try and look back deeper into the past the cause and effect of events will become less clear, and a description of why each event happened will be less apparent and more contrived, more and more events will seem to just emerge due to luck from a more chaotic state. This tipping point is the top of the hill.

If we could look back further the events would seem almost magical, things would seem to emerge by change, you might see a chaotic galaxy splitting neatly into two ordered ones, in short it would look like time in reverse. This is because newton/einstein’s physics is time reversible.
So a good way to make sense of this is to distinguish objective time (the horizontal axis below) from subjective time, which always points down the hillside:

Why should subjective time run downhill?
It guarantees that entropy/disorder will increase over time. Otherwise, it may take some clever experiments to explore the relationship between entropy and time, but I will hazard a theory here…

Our perception of time is probably mostly to do with us having memories of the past and being able to store and then re-simulate them in our heads. If you keep memories of up the slope then this has more order and an event uses less information, whereas down the hill events would take more information than our current experience. There is a sense that you can fully know the uphill (past) but are not able to understand downhill (future) as it is more complicated than your current state.

You might even use this idea to come up with a unit of subjective time, the time taken for you to be able to store an event twice in the space that you can currently store an event. This idea lets us answer a second puzzle, how long does the universe last?

If time is perceived in proportion to increase in entropy, then as you near the bottom of the hill, the gradient probably drops off and time will pass faster… i.e. the universe won’t “get boring”… at some point you will hit another upwards hill and you won’t perceive time after that.

Monday, January 10, 2011

Reinterpretation of 2nd law of thermodynamics

It is often quoted that entropy only increases due to the 2nd law of thermodynamics, this isn’t really true in the general case, and the real behaviour is, I think, more interesting and revealing.

The 2nd law is concerned with what happens to certain measurements over time, such as the temperature of an object or the dispersion of a liquid, these measurements are called macroscopic measurements as they measure the collective state, as opposed to ‘microscopic’ measurements which measure the actual exact state of every atom in the object.

Take for example a tin of water-based paint which is white paint in the top half and black in the bottom half. If you leave it for a while it will begin to disperse and eventually the whole tin will reach a grey colour where it will be in equilibrium. The macroscopic measurement is the amount of separation, we could measure it as the vertical distance of the average particle of white paint from half way up the tin:

The 2nd law states that the amount of disorder (called the entropy) increases over time, i.e. the separation level (s) in this tin of paint will go down, which as you can see above, it does. This is because the number of microscopic states (position of the black and white paint particles) for a low amount of separation is far far greater than for a high separation. It is simply far more likely that the set of particles will find their way into the grey state.

To study this more carefully you can grid the paint tin as say 100*100*200 particle positions, and allow each particle to swap positions with one of its neighbours randomly, if you then plot a graph of the dispersion level with time, from any random start point, you actually find that the overall behaviour follows a shape like so:
The usual case for this tin of paint is that its s is 0, it is grey. Occasionally it will raise to a higher level (more ordered) and then come back down again making a little hill. The larger hills are far less frequent than the smaller hills, the resulting shape is a fractal pattern quite different to a single gradient as the 2nd law is often envisaged. This pattern remains pretty much regardless of the actual equations of motion used.

The reason why we usually think of order as always increasing with time is that are examples almost always involve something exceptionally ordered, such as the tin of paint on the left.
The way to think of this on the graph is that, if you searched the graph for a point high enough to represent the separated black and white paint, then you would find it at the top of a very large hill, and as such the projection forwards in time (the slope to the right of the hill top) would have to be decreasing.

Because each larger peak is so much less frequent than smaller peaks, if you find any point of a particular height it is overwhelmingly likely to be the top of a peak as in the above graph. The interesting thing is that this means that, if for instance you search the graph and find a separation level equal to the fairly separated paint 2nd from left in the picture, then if you simulate it backwards in time, the order also decreases. This is perhaps surprising at first, it means that an almost separated tin of paint is more likely to have arrived there ‘by accident’ from a tin of grey paint than to have arrived by being the dispersal of the separated paint on the left tin.

This goes against common thinking, which is that each level of order has arrived from a higher level of order. It is the common thinking that everything has a good reason for its existence, and something or other created it. Because separated paint will inevitably show a dispersion in the middle then a tin with dispersion in the middle must have come from separated paint left for a few hours. This chain of events from order to disorder is common thinking, and it isn’t actually true.

Does this mean that if I go to my garden shed and find a slightly separated tin of paint, that it just got their by accident from an unseparated state? No, because it is still far more likely that the paint arrived in that state by a person putting it there, than by accident.

Does it mean that our history in the universe is actually less ordered than it is now? did we all just appear from some random dust in the last year? Well we have historical records showing order in the past (e.g. photos prior to last year), and even though it is relatively unlikely to have come from a more ordered state, it is much more unlikely to have come from a disordered state and somehow have photos that show it being ordered. In other words, correlating evidence shows us that things have been more ordered in the past, but that doesn’t mean they have to continue to be more ordered in the deeper past.

So my conclusion is that, when we look deeper and deeper into the past, we are looking up to the top of a very big hill like in the graph above. The closer we get to the top, the more difficult the reasoning will become in how events unfolded. That is because they will become less and less causational (downwards slope) and more and more emergent (upwards slope), the other side of this slope will seem like a miracle, as chaos will seem to come together in just the right way, is this miracle actually just time running backwards?